Llm

Blog posts tagged “LLM”


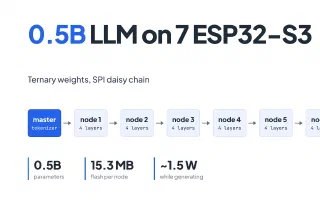
Running a 0.5B LLM on Seven ESP32-S3 Boards

ESP32 BitNet Edge AI

How an open-source cluster of seven ESP32-S3 microcontrollers splits a Qwen2-0.5B model into 1.58-bit ternary layers, why it fits in 16 MB of flash per board, and why it is slow.

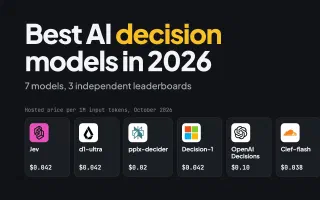
Best Open Source Jev Alternatives: 7 Self-Hosted Decision Models

AI Models Open Source Self-Hosted AI

Open-weight decision models now beat TypeSafe's Jev on both independent leaderboards. Karpo Decision 31B, GLiDE, vLLM-SR d3, Mammoth-1, pplx-decider v1.3, Kev and Laya compared on Decision Index 0.4.1 and Artificial Analysis v2 scores, licenses, and the GPU each one needs to self-host.

TypeSafe Jev: Top 3 Use Cases and How It Compares to OpenAI and Anthropic Models

AI Models API LLM

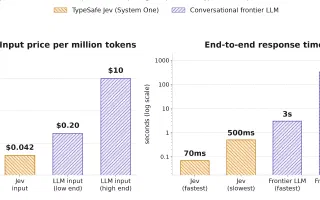
TypeSafe's Jev is a System One model that returns typed decisions instead of text: 70-500ms latency, $0.042 per million input tokens with output free, and 0% structured-output errors. Here are the three jobs it actually fits, the honest benchmark picture against GPT-6 Astra and Claude, and the tasks where it is the wrong tool.

How to Self-Host Langflow and Access It Remotely

Langflow AI Agents Self-Hosted

Learn how to install and self-host Langflow locally using pip, uv, or Docker, and make it remotely accessible from anywhere using Pinggy. Build and deploy custom AI agents without cloud lock-in.