Best Open Source Self-Hosted Text-to-Speech Models in 2026
Updated on Aug 26, 2026 · 32 min read
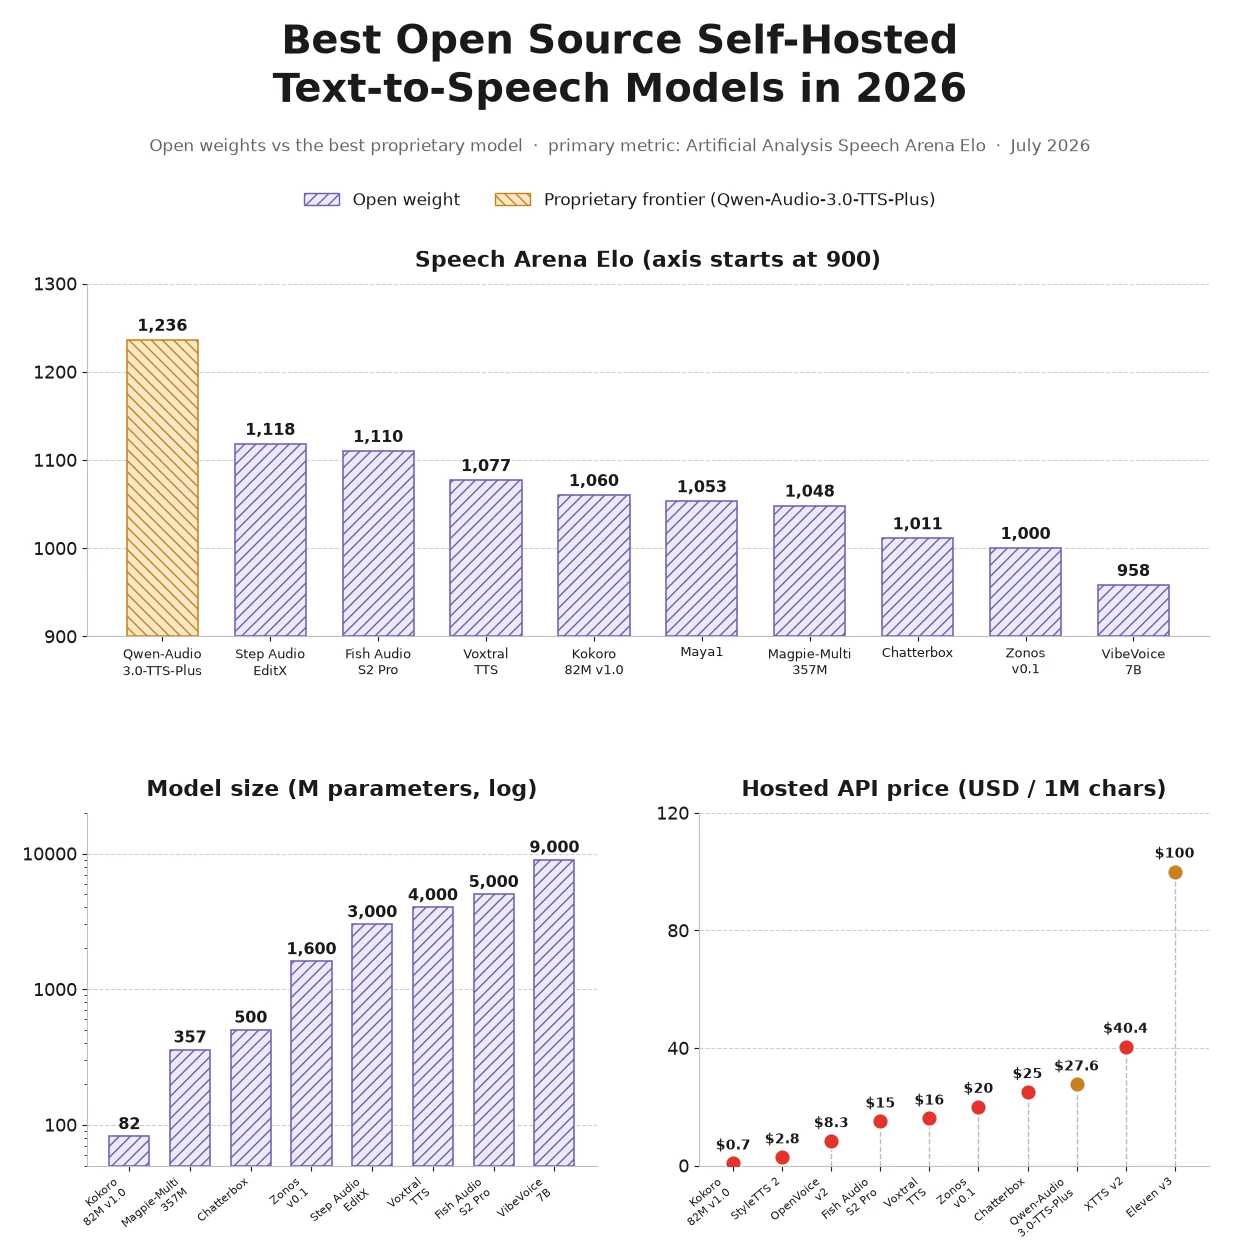
Text-to-speech has quietly become one of those things every project eventually needs - narration for a video, a voice for an agent, an accessibility layer, notifications that don’t need a screen. For most of the last decade the practical answer was to send your text to somebody’s API and pay per character, because the models you could run yourself sounded like a satnav.
That’s no longer true, and as of last week it isn’t even close. Breeze TTS 2, released on August 25, 2026, scores 1,215 Elo on the Artificial Analysis Speech Arena - beating ElevenLabs Eleven v3 (1,177), the model ElevenLabs charges $100 per million characters for. It’s the first open-weight model to clear ElevenLabs’ flagship on that board, six weeks after the best open weights sat 59 points below it, and you can run it on a 12GB card.
The other end of the range is just as strange: Kokoro is 82 million parameters, runs on a laptop CPU, is Apache 2.0, and blind listeners still pick it over Microsoft’s 9-billion-parameter VibeVoice. Every model here runs on a single GPU, and several run on hardware you already own.
The frontier is still ahead, just not as far ahead. Cartesia’s proprietary Sonic 3.6 tops the overall board at 1,283 against 1,215 for the best open weights - a 68-point gap where it was 118 in July. And the economics aren’t close: the best-value open model runs about $0.70 per million characters hosted against $100 for ElevenLabs v3, and nothing but electricity if you run it yourself.
This guide covers the open-weight TTS models worth self-hosting in August 2026, what each is good at, the licensing traps (they got worse this summer), and the tooling to deploy them.
Summary
Top Open-Weight TTS Models (blind listening tests, August 2026):
- Breeze TTS 2 - 1,215 - beats ElevenLabs v3; cloning, voice design and direction; non-commercial - Hugging Face
- Fish Audio S2 Pro - 1,125 - inline
[tag]prosody, 80+ languages, non-commercial - fish.audio/s2 - Step Audio EditX - 1,102 - emotion editing, Apache 2.0, best pick you can ship - Project page
- Voxtral TTS - 1,082 - 3-second cloning, best open weights on the controlled-voice board - Mistral
- Magpie-Multilingual 357M - 1,066 - 9 languages, commercial-safe - NVIDIA
- Kokoro 82M v1.0 - 1,060 - runs on a CPU, Apache 2.0, no cloning - GitHub
- Maya1 - 1,045 - design a voice from text, Apache 2.0 - mayaresearch.ai
- Higgs Audio V3 TTS - 1,042 - 100+ languages with published WER, non-commercial - Hugging Face
- Chatterbox - 1,020 - MIT, 23 languages, emotion control - resemble.ai
- Zonos-v0.1 - 1,000 - Apache 2.0, 44kHz, 6GB VRAM - Zyphra
Three the Speech Arena hasn’t scored, two of them Apache 2.0:
- Qwen3-TTS - Apache 2.0, 0.6B/1.7B, 10 languages, 5M+ downloads - GitHub
- VoxCPM2 - Apache 2.0, 2B, 30 languages, 48kHz, runs on CPU - GitHub
- GLM-TTS - MIT weights, Chinese/English, 0.89 CER - GitHub
Watch the license, not the marketing. The top two on the board are non-commercial despite being called open source, and so is #8. Step Audio EditX (#3) is the highest-ranked model you can ship; Qwen3-TTS and VoxCPM2 are the strongest Apache 2.0 options overall.
There is no DeepSeek TTS model. DeepSeek V4 is text-only. Qwen3-TTS and GLM-TTS are the Chinese-lab open TTS models that actually exist.
Best Self-Hosting Tools:
- LocalAI - broadest model coverage, OpenAI-compatible
- vLLM-Omni - production GPU serving for new-generation TTS
- llama.cpp-omni - VoxCPM2 in GGUF on CPU, Metal, CUDA or Vulkan, no PyTorch
- Kokoro-FastAPI - the fastest path to a working endpoint
Where open weights stand today
The ranking comes from the Artificial Analysis Speech Arena, where listeners hear two clips of the same text without knowing which model made them and pick the better one. It’s the most useful signal in TTS, because it measures whether the output sounds good to a human rather than a metric a vendor can train against.
Breeze TTS 2 broke the pattern. For the past year the top of the open-weight board was a scrum inside a 125-point band; Breeze cleared #2 by 90 Elo in one release and landed 6th out of 100 models overall, ahead of ElevenLabs Eleven v3 and StepFun’s own closed StepAudio 2.5 TTS. Behind it, seven models from Fish S2 Pro down to Higgs Audio V3 land inside 85 points of each other while ranging from 82M to 4B parameters and disagreeing completely about what a TTS model is even for.
That spread is the real headline. Size has almost stopped predicting quality. Kokoro sits 6th at 82M, ahead of models fifty times larger, and NVIDIA’s Magpie does nine languages in 357M and outranks it. The trillion-parameter arms race that defines open-weight LLMs simply isn’t happening here.
Two leaderboards, two different answers
The main Provider Voices arena lets each model compete with its own built-in voices, so you’re voting on the model and the voices its makers picked. The Controlled Voice Arena, added in July 2026, hands every model the same 8 cloned voices instead. It only includes models that can clone, so Kokoro, Maya1 and Magpie aren’t on it by construction. The reshuffle is significant:
| Model | Provider Voices | Controlled Voice |
|---|---|---|
| Breeze TTS 2 | 1,215 (1st) | 1,002 (2nd) |
| Fish Audio S2 Pro | 1,125 (2nd) | 1,000 (3rd) |
| Voxtral TTS | 1,082 (4th) | 1,010 (1st) |
| Higgs Audio V3 TTS | 1,042 (8th) | 958 (4th) |
| Chatterbox | 1,020 (9th) | 927 (5th) |
Breeze’s 90-point lead collapses to a three-way tie with Voxtral and Fish when everyone clones the same voices, which says something practical: BreezeBlue’s own voices are outstanding and its cloning is average. Pick your board by use case. Shipping stock voices? Provider Voices. Cloning your own narrator or customer? Controlled Voice, where Voxtral TTS wins. Closed models hold up better under the control, incidentally: Sonic 3.6 leads it at 1,120, a 110-point gap over open weights against 68 on the provider board.
Open-weight leaderboard (August 2026)
| Model | Creator | Elo | License |
|---|---|---|---|
| Cartesia Sonic 3.6 (proprietary, for reference) | Cartesia | 1,283 | Closed |
| Breeze TTS 2 | BreezeBlue | 1,215 | Research (non-commercial) |
| ElevenLabs Eleven v3 (proprietary, for reference) | ElevenLabs | 1,177 | Closed |
| Fish Audio S2 Pro | Fish Audio | 1,125 | Research (non-commercial) |
| Step Audio EditX | StepFun | 1,102 | Apache 2.0 |
| Voxtral TTS | Mistral | 1,082 | CC BY-NC 4.0 |
| Magpie-Multilingual 357M (v2602) | NVIDIA | 1,066 | NVIDIA Open Model |
| Kokoro 82M v1.0 | hexgrad | 1,060 | Apache 2.0 |
| Maya1 | Maya Research | 1,045 | Apache 2.0 |
| Higgs Audio V3 TTS | Boson AI | 1,042 | Research (non-commercial) |
| Chatterbox | Resemble AI | 1,020 | MIT |
| Magpie-Multilingual 357M (Jan 2026) | NVIDIA | 1,004 | NVIDIA Open Model |
| Zonos-v0.1 | Zyphra | 1,000 | Apache 2.0 |
| VibeVoice 7B | Microsoft | 969 | MIT (withdrawn) |
| OpenVoice v2 | MyShell | 954 | MIT |
| XTTS v2 | Coqui | 920 | CPML (non-commercial) |
| StyleTTS 2 | Li et al. | 892 | MIT + conditions |
| MetaVoice v1 | MetaVoice | 844 | Apache 2.0 |
Two proprietary models are included as reference points: Cartesia Sonic 3.6, the overall leader, and ElevenLabs Eleven v3, which Breeze TTS 2 now outranks. For the current scores and the full 100-model list, visit the Speech Arena leaderboard directly.
Best Open Source TTS Models
1. Breeze TTS 2 (BreezeBlue) - the new leader, and it beats ElevenLabs v3
Breeze TTS 2 was announced on August 7, 2026 and the weights went up on August 25, rewriting the top of this list two days before we updated it: 1,215 Elo, 90 points clear of Fish Audio S2 Pro, 6th out of 100 models open and closed together, and the first open-weight model to outrank ElevenLabs Eleven v3 (1,177) - the $100-per-million-characters flagship.
It’s a 3B transformer with three distinct ways to get a voice, which is more than anything else here offers: cloning from reference audio, Voice Design that builds a speaker from a written description with no reference at all, and Voice Direction that clones a voice and steers its tone, emotion and pace at once. That last one is the interesting bit, since most models make you pick between copying a speaker and directing a performance. Vocal events go inline as (laugh), (cough), (sigh) in English or [笑], [咳嗽], [叹气] in Chinese.
It’s cheap to run for something at this level: about 7.7GiB of VRAM for eager inference, so a 12GB card is the stated minimum, and the fast path wants ~14.4GiB and a 24GB card. On an H100 with the fast path warmed up, BreezeBlue reports under 40ms time-to-first-audio and RTF 0.32 (~3.1x real time).
Three real caveats.
The license is non-commercial. The inference code is Apache 2.0; the weights are under the BreezeBlue Research and Non-Commercial License, and commercial use needs written authorization from RESONIA, INC.
The language claim doesn’t hold up. breezeblue.ai advertises “50 languages, with accent control.” The Hugging Face model card tags exactly two, en and zh, and documents vocal-event tags for those two only. Treat anything past English and Mandarin as untested.
The 90-point lead is partly its voices, not its model. On the Controlled Voice Arena, where every model clones the same 8 voices, Breeze scores 1,002 against Voxtral TTS at 1,010 and Fish S2 Pro at 1,000 - a three-way tie. BreezeBlue’s built-in voices are excellent; its cloning is ordinary.
It’s also two days old, with no vLLM-Omni support yet, so serving means the PyTorch CLI, the streaming API, or the Docker image.
Key Specs
- Architecture: 3B transformer, streaming, CFG guidance scale
- License: Apache 2.0 code, BreezeBlue Research and Non-Commercial License weights
- Released: announced August 7, 2026; weights August 25, 2026
- Languages: English and Mandarin documented (vendor claims 50)
- Speech Arena Elo: 1,215 provider-voice / 1,002 controlled-voice
- Self-hosting: 12GB VRAM minimum (~7.7GiB eager), 24GB for the fast path; PyTorch CLI or Docker
- Limits: Non-commercial weights, no vLLM-Omni support yet, days-old ecosystem
2. Fish Audio S2 Pro - inline prosody tags, non-commercial license, and the best cloning
Fish Audio S2 Pro (March 2026) held the #1 spot for most of the summer and now sits second at 1,125 Elo, up 15 points since July as the votes piled up. It has the most pleasant control surface of anything in this list. You write prosody directly into the text as free-form tags:
[clears throat] Hey chat, how do I solve merge conflicts again?
[whisper in small voice] I definitely knew the answer yesterday. [exhale]
There are 15,000+ recognized tags, and they accept natural-language descriptions rather than a fixed enum, so [pitch up] and [flirty] both work - much lower friction than fiddling with conditioning vectors.
Architecturally it’s a Dual-AR design: a 4B “Slow AR” built on Qwen3-4B predicts semantic tokens, and a 400M “Fast AR” fills in acoustics across 10 RVQ codebooks. Fish reports 0.54% WER on the Seed-TTS Chinese test set and an 81.88% win rate on EmergentTTS-Eval, with 80+ languages in tiers (Japanese, English and Chinese are tier 1). Serving is SGLang-based: RTF 0.195 and ~100ms time-to-first-audio on a single H200.
The catch is the license. Despite the “now open-source” headline on the product page, the weights are under the Fish Audio Research License - free for research, commercial use requires a separate agreement. Watch out for one confusion: the arXiv paper is CC BY 4.0, which is the paper’s license, not the weights’. Fish doesn’t publish a VRAM minimum.
Key Specs
- Architecture: Dual-AR - 4B Slow AR (Qwen3-4B based) + 400M Fast AR, 10 RVQ codebooks
- License: Fish Audio Research License (non-commercial)
- Released: March 9, 2026
- Languages: 80+ (tiered)
- Speech Arena Elo: 1,125 provider-voice / 1,000 controlled-voice
- Vendor benchmarks: 0.54% WER (Seed-TTS test-zh), 81.88% EmergentTTS-Eval win rate
- Self-hosting: SGLang or vLLM-Omni; RTF 0.195 on a single H200; no published VRAM floor
3. Step Audio EditX (StepFun) - the best pick you can actually ship
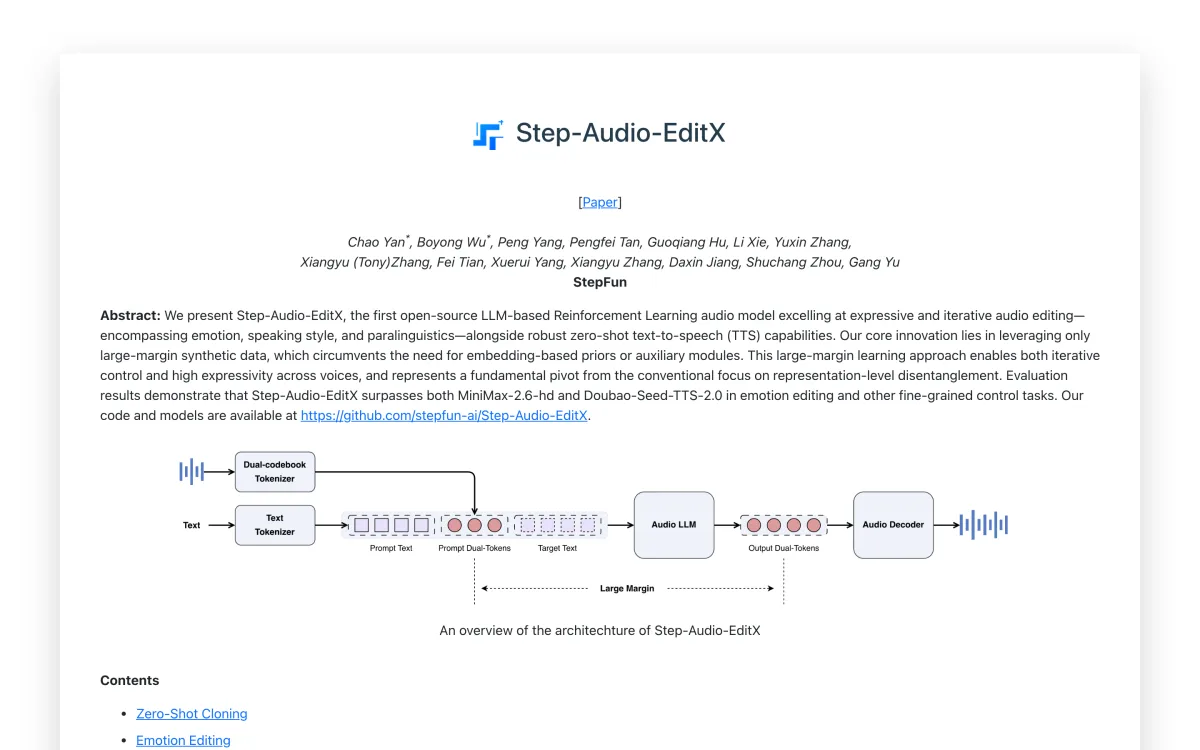
Step Audio EditX was #1 in our July edition at 1,118 Elo. It’s now third at 1,102 - it didn’t get worse, the board got busier and its score drifted down 16 points as more votes came in. What matters more is that it’s the highest-ranked open-weight model you can put in a commercial product, because both models above it are non-commercial and it’s Apache 2.0. StepFun shipped the weights in November 2025 and improved the paralinguistics in January 2026.
The interesting thing is that it isn’t really a TTS model with editing bolted on - it’s an audio editing model that also does TTS. A dual-codebook tokenizer turns speech into discrete tokens, a 3B audio LLM manipulates them, and a flow-matching decoder turns them back into waveform. Because edits happen in token space rather than through waveform DSP, you can iteratively refine a take: generate, adjust the emotion, adjust it again.
In practice that buys you 14+ emotions, 30+ speaking styles, 20+ paralinguistic tags (breathing, laughter, sighing), zero-shot cloning, and utilities like denoise and silence trimming. StepFun reports 81.6% emotion accuracy in Chinese after three refinement iterations.
The tradeoffs are real. It’s designed for clips under 30 seconds per inference, so long-form narration means chunking the text yourself, and language coverage is narrow (Mandarin, English, Sichuanese, Cantonese, Japanese, Korean). Upstream has also gone quiet: the last commit was April 2026 and StepFun’s attention has moved to the API-only StepAudio 2.5 TTS (1,208 Elo, closed). Not a reason to avoid it, but don’t expect a v2.
Key Specs
- Architecture: Dual-codebook tokenizer, 3B audio LLM, flow-matching decoder
- License: Apache 2.0
- Released: November 2025, updated January 2026
- Languages: Mandarin, English, Sichuanese, Cantonese, Japanese, Korean
- Speech Arena Elo: 1,102 (highest commercially licensed open weights in this guide)
- Self-hosting: 12GB VRAM minimum (tested on an L40S), vLLM supported
4. Voxtral TTS (Mistral) - the best 3-second voice cloning
Voxtral TTS (March 23, 2026) scores 1,082 Elo and is the most straightforward model here to actually run: a single GPU with 16GB VRAM, served through vLLM Omni.
It is also, quietly, the best open-weight cloner in the business. On the Controlled Voice Arena it leads all open weights at 1,010, ahead of Breeze TTS 2 (1,002) and Fish S2 Pro (1,000). If your job is “make this specific voice say this text,” that’s the board to read, and Voxtral wins it.
It’s three pieces totalling ~4B parameters: a 3.4B decoder based on Ministral 3B predicts semantic tokens from text plus a voice prompt, a 390M flow-matching transformer handles acoustics, and a 300M neural codec produces the waveform at 24kHz.
Its party trick is cloning from about three seconds of reference audio with no transcript required, inferring prosody and emotion from the voice prompt rather than needing tags. Mistral reports a 68.4% human preference win rate against ElevenLabs Flash v2.5 on blind zero-shot cloning, and documents performance properly for once: on one H200, RTF 0.103 at one concurrent request (~9.7x real-time), degrading to 0.302 at 32 concurrent.
Two caveats. It’s CC BY-NC 4.0, so non-commercial. And Mistral publishes no WER or speaker-similarity numbers, saying they prioritized human naturalness evaluation - defensible, but you can’t line it up against Fish’s figures.
Key Specs
- Architecture: 3.4B decoder (Ministral 3B based) + 390M flow-matching acoustic model + 300M codec
- License: CC BY-NC 4.0 (non-commercial)
- Released: March 23, 2026
- Languages: 9 - English, French, German, Spanish, Dutch, Portuguese, Italian, Hindi, Arabic
- Speech Arena Elo: 1,082 provider-voice / 1,010 controlled-voice (best open weights)
- Self-hosting: Single GPU, 16GB+ VRAM, vLLM Omni 0.18.0+; RTF 0.103 on an H200
5. NVIDIA Magpie-Multilingual 357M - the commercial-safe multilingual pick
Magpie-TTS Multilingual is 357M parameters, covers 9 languages, and ships under the NVIDIA Open Model License, which permits commercial use. Small, multilingual and commercially usable is a rarer combination than it should be.
It’s a transformer encoder-decoder predicting 8 codebooks of NanoCodec tokens at 22kHz, trained on 38k hours, with CTC-based attention priors to enforce monotonic alignment - the standard fix for the skipping and repeating autoregressive TTS is prone to.
The newer checkpoint (v2602, which added Hindi and Japanese) now scores 1,066, up 62 Elo from the January checkpoint’s 1,004 - a useful reminder that these models get meaningfully better between point releases, and enough to move Magpie above Kokoro since our July edition. On the January checkpoint NVIDIA reports 0.34% CER and 0.835 speaker similarity on LibriTTS test-clean, degrading on the non-English CML sets (French: 2.70% CER, 0.703 SV-SSIM).
Two deliberate omissions before you pick this. Zero-shot cloning was removed - the model card says plainly “we have removed zero-shot capabilities,” so you get 5 fixed speakers and nothing else - and emotional speech is gated to the enterprise NIM. That’s the point, presumably: it’s aimed at voice agents and brand ambassadors, where you want one consistent voice and no ability to impersonate anyone. If you want cloning from NVIDIA, that’s a separate model, Magpie TTS Zeroshot, at 926 on the Controlled Voice Arena.
Also note the 20-second cap per inference in standard mode; long-form mode uses a sliding window and is English-only.
Key Specs
- Architecture: Transformer encoder-decoder, 8-codebook NanoCodec at 22kHz, 357M params
- License: NVIDIA Open Model License (commercial use permitted)
- Released: January 2026 (v2512), March 3, 2026 (v2602, adds Hindi + Japanese)
- Languages: 9 - English, Spanish, German, French, Italian, Vietnamese, Mandarin, Hindi, Japanese
- Speech Arena Elo: 1,066 (v2602 checkpoint) / 1,004 (Jan 2026)
- Self-hosting: NeMo Framework 25.11; A10/A30/A100/H100; no published VRAM figure
- Limits: No voice cloning, no emotion control in the open weights, 20s per inference
6. Kokoro 82M v1.0 - 82 million parameters, still in the top six
Kokoro has no business being here. It’s 82M parameters - about 1/60th the size of Fish Audio S2 Pro - and it scores 1,060 Elo, ahead of Maya1 (3B), Higgs Audio V3 (4B), Chatterbox and VibeVoice 7B, with a score that hasn’t moved a point since July. It’s a StyleTTS 2 architecture with an ISTFTNet vocoder, no diffusion, trained on “a few hundred hours” of permissively licensed and synthetic audio. It runs in under 2GB of VRAM, or CPU-only in about 4GB of RAM via ONNX, and it’s Apache 2.0. It’s also, by a distance nobody is closing, the most-used open TTS model in the world: 12 million Hugging Face downloads on one checkpoint, more than twice the entire Qwen3-TTS family.
The tradeoff is stark: no voice cloning and no emotion control. You get 54 preset voices across 8 languages, and that’s the whole menu. If your use case is “read this text in a decent voice, cheaply, at scale” - audiobooks, notifications, accessibility, an app’s narrator - Kokoro is the correct answer and nothing else is close on cost. If you need a specific person’s voice or a specific emotional read, it cannot do it at any price.
Two practical notes. The commonly quoted speed figures (~0.03 RTF on an A100, ~2.4x real-time on CPU) come from third-party benchmarks, not hexgrad - there are no official numbers. And the reference repo is frozen at August 2025, with the ecosystem moved to kokoro-onnx and Kokoro-FastAPI. The model works; the repo just stopped needing changes. Note also that Kokoro has no official website - the model card disclaims any site with “kokoro” in the root domain, so GitHub and Hugging Face are the only canonical homes.
Key Specs
- Architecture: StyleTTS 2 + ISTFTNet vocoder, decoder-only, 82M params
- License: Apache 2.0
- Released: January 27, 2025
- Languages: 8 languages, 54 preset voices
- Speech Arena Elo: 1,060
- Self-hosting: Under 2GB VRAM, or CPU-only via ONNX; Apple Silicon MPS supported
- Limits: No voice cloning, no emotion control
We have a full walkthrough of running this one on free hardware: Self-Hosting Text-to-Speech AI for Free on Google Colab.
7. Maya1 - describe the voice you want in words
Maya1 (November 2025, Apache 2.0) scores 1,045 Elo and takes a genuinely different approach to voice control. Instead of cloning from a reference clip, you describe the voice you want:
<description="40-year-old male, warm, low pitch, conversational">
That’s promptable voice design, and it sidesteps the consent problem reference-audio cloning creates - you’re not copying anyone, you’re specifying a synthetic speaker. It’s a 3B Llama-style decoder feeding a SNAC neural codec at 24kHz mono, with 20+ inline emotion tags and streaming at a claimed sub-100ms latency on vLLM. It wants 16GB+ VRAM, and community GGUF quants exist if you want to go smaller.
Two things to know. It’s English-only, with multilingual listed as future work. And Breeze TTS 2, Qwen3-TTS VoiceDesign and VoxCPM2 all do promptable voice design now, so Maya1’s distinguishing feature is no longer unique - its remaining edge is Apache 2.0 licensing. Maya Research still claims #2 among open-weight voice models; that dates from its November 2025 launch and it now sits 7th.
Note that mayaresearch.ai is the only official page - maya1.org and similar high-ranking results are unaffiliated SEO sites.
Key Specs
- Architecture: 3B Llama-style decoder + SNAC neural codec, 24kHz
- License: Apache 2.0
- Released: November 2025
- Languages: English only (multi-accent)
- Speech Arena Elo: 1,045
- Self-hosting: Single GPU, 16GB+ VRAM, vLLM; sub-100ms streaming latency claimed
8. Higgs Audio V3 TTS (Boson AI) - 100+ languages with the error rates published
Higgs Audio V3 TTS (June 4, 2026) scores 1,042 Elo with 219,000 Hugging Face downloads - respectable traction for a model three months old. Boson AI also calls it “Higgs TTS 3”; same 4B model.
Its pitch is language coverage, and unlike most such claims it comes with numbers. The model card tags 100 languages, Boson evaluated 111, and they report single-digit WER/CER across the set: 1.11 WER on SeedTTS (2 languages), 2.74 on MiniMax-Multilingual (32), 3.61 on their own 111-language benchmark. Roughly 85 of those clear the <5% WER bar they call production quality. Nothing else here publishes a multilingual table that wide.
Control is inline and mid-utterance: 21 emotion tags, styles including singing, shouting and whispering, sound effects, plus speed, pitch and pause markers. Zero-shot cloning from a reference clip, 8k token context.
The license follows the now-familiar pattern: the code is Apache 2.0, the weights are under the Boson Higgs TTS 3 Research and Non-Commercial License, and anything revenue-generating needs a separate agreement. Boson’s prohibited-use list is more specific than most - cloning without consent, impersonation, fraud, election deception, biometric surveillance. The hosted API is in free public preview, so you can evaluate it without a GPU.
Two gaps. Boson publishes no VRAM figure anywhere official, which for a 4B model probably means 12-16GB but you’ll have to measure it. And serving means SGLang-Omni or Boson’s API, not vLLM-Omni - though SGLang-Omni had day-zero support and publishes throughput: ~15 requests/second at RTF 0.26 on a single H100.
Key Specs
- Architecture: 4B, Qwen3-based multimodal backbone, 8k context
- License: Apache 2.0 code, Boson Higgs TTS 3 Research and Non-Commercial License weights
- Released: June 4, 2026
- Languages: 100+ tagged, 111 evaluated, ~85 at <5% WER
- Speech Arena Elo: 1,042 provider-voice / 958 controlled-voice
- Self-hosting: SGLang-Omni; no published VRAM floor
9. Chatterbox (Resemble AI) - MIT, 23 languages, emotion exaggeration
Chatterbox scores 1,020 Elo and is the best-rounded permissively licensed option: MIT, 0.5B parameters, cloning from ~5 seconds of audio, and an emotion exaggeration control that Resemble claims was an open-source first. At 26k GitHub stars and 1.8 million downloads it’s the most popular model on the leaderboard after Kokoro, and the repo is still moving (last commit July 2026).
The family has grown well past the original May 2025 English release: Multilingual (September 2025) covers 23 languages, v3 (June 2026) pushes to ~25 with 6 tuned single-language packs. Chatterbox Turbo is the one for real-time work - 350M parameters, 75ms latency, ~6x real-time via a single-step mel decoder - plus paralinguistic tags ([laugh], [sigh], [whisper]).
Resemble publishes blind-eval win rates and, refreshingly, the losses too: Turbo beats ElevenLabs Turbo v2.5 65.3% and VibeVoice 7B 59.1%, but ties Cartesia Sonic 3 at 49.8%. That’s more credibility than most vendor tables earn.
One thing to be aware of: every Chatterbox output carries PerTh neural watermarking, embedded at generation. A feature if you care about provenance, a constraint if you don’t want an inaudible signal in your audio. No official VRAM figure.
Key Specs
- Architecture: 0.5B Llama-style backbone, trained on ~500k hours
- License: MIT
- Released: May 2025 (English), Sept 2025 (multilingual), June 2026 (v3)
- Languages: 23 (multilingual), ~25 in v3
- Speech Arena Elo: 1,020 provider-voice / 927 controlled-voice
- Self-hosting:
pip install chatterbox-tts; ~200ms latency, Turbo at 75ms; no published VRAM floor
10. Zonos-v0.1 (Zyphra) - Apache 2.0, 44kHz, runs on 6GB
Zonos-v0.1 (February 10, 2025) sits at exactly 1,000 Elo and remains a solid Apache 2.0 workhorse, mainly because it’s the lowest-VRAM cloning model here. Zyphra released two 1.6B variants, a pure transformer and an SSM hybrid built on Mamba2, trained on ~200k hours and outputting natively at 44kHz. It held the sample-rate crown until VoxCPM2 shipped 48kHz in April 2026, which is now the better answer if fidelity is why you were looking at Zonos.
It clones from a 10-30 second sample with conditioning knobs for speaking rate, pitch, max frequency and emotion, runs on 6GB+ VRAM with a Gradio UI and Docker, and hits roughly 2x real-time on a 4090. The hybrid variant needs an RTX 3000-series or newer.
Two honest caveats. Zyphra publishes no quantitative benchmarks at all, conceding in the announcement that audio quality is hard to quantify. And it’s still labelled v0.1 beta eighteen months on, with languages beyond English, Japanese, Chinese, French and German in the training data but not robust.
Key Specs
- Architecture: 1.6B transformer or 1.6B Mamba2 SSM hybrid, 44kHz output
- License: Apache 2.0
- Released: February 10, 2025
- Languages: English, Japanese, Chinese, French, German (others unreliable)
- Speech Arena Elo: 1,000
- Self-hosting: 6GB+ VRAM; hybrid needs RTX 3000-series or newer; ~2x real-time on a 4090
Strong open models the Speech Arena hasn’t scored
The Elo table above is the best signal in TTS, but it is not a census. Artificial Analysis adds a model when there’s an endpoint to test and enough votes to rank it, and three good open-weight models have slipped through that gap - two of them Apache 2.0, which given that the board’s top two are non-commercial makes them the most important omissions in this guide.
Treat this section differently: these are vendor-reported numbers, not blind listening tests, so discount them accordingly. But 3 million downloads is its own kind of signal.
Qwen3-TTS - Apache 2.0, and the most-downloaded model that isn’t Kokoro
Qwen3-TTS (Alibaba, January 22, 2026) is one of the two models people are actually running. The 1.7B base checkpoint has 3.0 million Hugging Face downloads and the CustomVoice variant another 2.4 million - far past anything on the leaderboard except Kokoro and Chatterbox - and it’s the default TTS in Hugging Face’s speech-to-speech pipeline. Both the weights and the tokenizers are Apache 2.0.
It ships as a matrix rather than a single model: 0.6B and 1.7B sizes, each in Base, CustomVoice and VoiceDesign flavors. The 1.7B base download is 4.54GB, the 0.6B is 2.52GB. Ten languages, trained on more than 5 million hours of speech - 50x GLM-TTS’s set, which probably explains the multilingual robustness.
Alibaba’s claims are specific enough to check: lowest WER on the Seed-TTS zero-shot cloning benchmark with better speaker similarity than MiniMax and ElevenLabs across all 10 languages, and for VoiceDesign, state of the art on InstructTTSEval ahead of Hume and VoiceSculptor. vLLM-Omni serves all five variants directly and LocalAI has a backend.
The gap is the one that matters: no blind-listening score, so you can’t line it up against Breeze or Fish. The repo has also been quiet since March 2026, though for a model this widely deployed that reads more like “finished” than “abandoned.”
VoxCPM2 - Apache 2.0, 30 languages, 48kHz, and it runs on a CPU
VoxCPM2 (OpenBMB, April 2026, Apache 2.0) is the one to look at if the license section below worries you. It’s a 2B model covering 30 languages plus nine Chinese dialects, and it outputs at 48kHz - the highest sample rate in this guide, above Zonos’s 44kHz - from a 16kHz reference clip.
Architecturally it’s the odd one out: tokenizer-free, a diffusion autoregressive model working in an AudioVAE V2 latent space. Practically, it gives you three cloning modes with an honest tradeoff curve - Voice Design from a written description alone, Controllable Cloning with reference audio plus style guidance, and Ultimate Cloning that also wants a transcript and preserves the most detail. It scores 1.84% WER on Seed-TTS-eval English and 0.97% CER on the Chinese hard set, in about 8GB of VRAM at RTF ~0.30 on a 4090.
The deployment story is the best of anything here. Besides PyTorch and vLLM-Omni, there’s llama.cpp-omni, which runs it from GGUF weights on CPU, Metal, CUDA or Vulkan with no PyTorch anywhere in the stack. Kokoro has been the only real CPU option in this space for a year; this is the first serious model to join it, at 24x the parameters and 30 languages.
It’s also the most actively developed model in this guide: 36k GitHub stars, 311k downloads, commits within the last week.
GLM-TTS - Zhipu’s RL-tuned cloner, permissively licensed
GLM-TTS (Zhipu AI / zai-org, open-sourced December 2025) is the GLM family’s TTS entry, and it’s interesting for how it was trained rather than what it scores.
The architecture is conventional for 2026: a Llama-based LLM turns text into speech tokens, a flow-matching model turns those into a mel-spectrogram, a vocoder makes the waveform. What’s unusual is the post-training. Zhipu ran multi-reward reinforcement learning via GRPO with four reward functions - speaker similarity, character error rate, emotion and laughter - a technique that’s standard in open LLMs and almost unheard of in open TTS. It works: on seed-tts-eval Chinese the RL checkpoint gets 0.89 CER and 76.4 speaker similarity against 1.03 and 76.1 without RL, from only ~100k hours of training audio.
It clones from 3 to 10 seconds of prompt audio, takes hybrid phoneme-plus-text input for pronunciation control, streams, and runs on Ascend 910B NPUs as well as CUDA.
Two things to know. The licensing is permissive but inconsistently stated: the GitHub repo is Apache 2.0, the Hugging Face model card says MIT. Either way you can ship it. And it’s Chinese and English only, with no published VRAM figure, and the repo has been quiet since April 2026 - 1,055 stars against VoxCPM2’s 36,000 tells you where the community went.
There is no DeepSeek TTS model
Worth stating plainly, because it’s a common search and the answer is no. DeepSeek has never released a text-to-speech model. DeepSeek V4 (April 24, 2026, MIT licensed, 1.6T-parameter Pro and 284B Flash variants) is text-only. DeepSeek says multimodal is in development with no published timeline.
If you wanted a Chinese-lab open TTS model, the ones that exist are Qwen3-TTS and GLM-TTS above, plus Fish Audio S2 Pro and Step Audio EditX on the leaderboard. If you want V4 for text and a voice on top, pair it with Kokoro or Qwen3-TTS behind the same OpenAI-compatible server.
History and dead ends
Two things worth knowing before you go shopping in the bottom half of the leaderboard.
VibeVoice 7B - the one Microsoft took back
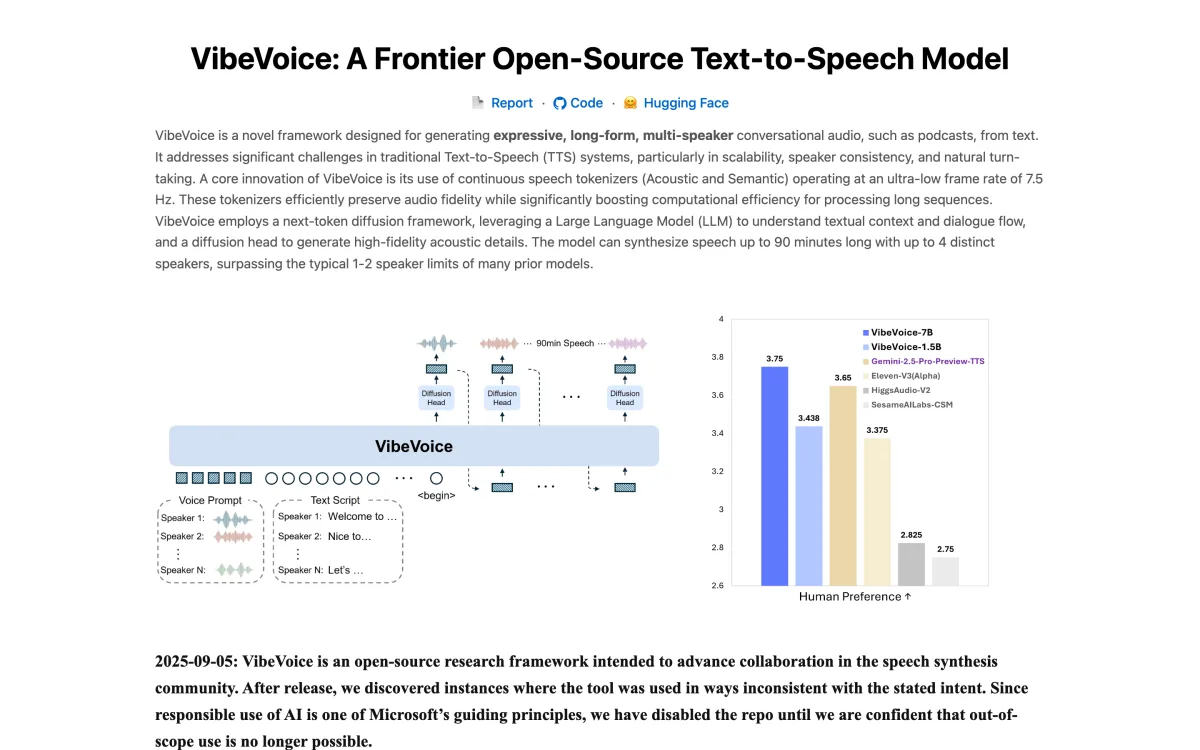
Microsoft released VibeVoice-7B-Preview on August 26, 2025 - a next-token diffusion model that could do 90 minutes of audio with 4 distinct speakers, well past everything else at the time. Ten days later it pulled it, citing use “inconsistent with the stated intent,” and stripped the weights and TTS code from its repos.
It didn’t work. The model was MIT licensed, so the community mirrors are entirely lawful and remain up. Microsoft withdrew a model it had already given away under a license that says you can’t take it back, and a year later its 969 Elo is still being computed from weights Microsoft no longer distributes.
One trap if you go looking: Microsoft’s current lineup includes VibeVoice-ASR (9B), which is speech recognition, not TTS. Searching “VibeVoice 7B” can easily land you on it. The “7B” in the original name was the LLM backbone; the full model was ~9B.
Four models to skip
The bottom of the leaderboard is a graveyard. None of these repos is archived, so you have to check commit dates rather than trusting the archive flag.
- OpenVoice v2 (MIT, 954 Elo) - still the only model with a decoupled tone-color converter, so you can clone in any language and speak in six. But quality is capped by its MeloTTS base speaker, and both layers are dormant since 2025.
- XTTS v2 (920 Elo) - widest language coverage here at 17, cloning from ~3 seconds. Its licensing is a mess, covered in the next section. Use the Idiap fork if you use it at all.
- StyleTTS 2 (892 Elo) - matters as an ancestor: Kokoro is built directly on it. Its own weights are English-only and the license is muddier than the “MIT” label suggests.
- MetaVoice v1 (Apache 2.0, 844 Elo) - skip it. Kokoro gives you Apache 2.0 at 82M with better output and a sixth of the VRAM. Last commit July 2024.
“Open weights” and “open source” are not the same thing here
Read the license rather than the landing page. TTS is worse about this than the LLM world, and it got measurably worse over the summer: the top two models on the board are both non-commercial, and so is #8. In July, #1 was Apache 2.0 and we could tell you the constraint was painless. It isn’t any more.
Fish Audio’s product page for S2 Pro reads “The most expressive voice AI ever made, now open-source.” The weights ship under the non-commercial Fish Audio Research License. Mistral’s Voxtral TTS is CC BY-NC 4.0. Both are genuinely downloadable and runnable on your own hardware; neither is open source in the OSI sense, and neither goes into a commercial product without a separate agreement.
The newer trick is worth learning to spot. Breeze TTS 2 and Higgs Audio V3 both ship their inference code under Apache 2.0 and their weights under a bespoke research-and-non-commercial license. GitHub’s sidebar reads “Apache-2.0” for both repos, Hugging Face reads license: other, and a glance at the repo will tell you the wrong thing. The license that binds you is the one on the weights, and you have to open the model card to find it.
The cautionary tale is XTTS v2. Its code is MPL-2.0, but its weights are under the Coqui Public Model License, which permits “only non-commercial use of a machine learning model and its outputs” - and Coqui the company shut down in January 2024 without answering a request to relicense them. The weights are now permanently non-commercial with nobody left who can sell you a commercial license; the canonical license URL at coqui.ai/cpml is a dead 404. The Idiap fork keeps the code alive (pip package coqui-tts), but a fork can’t relicense weights it didn’t train. The dead original repo has ~45k stars against the live fork’s ~2k, so search results will point you at the corpse.
If you need to ship commercially, the safe picks are Step Audio EditX (Apache 2.0), Qwen3-TTS (Apache 2.0), VoxCPM2 (Apache 2.0), Kokoro (Apache 2.0), Maya1 (Apache 2.0), GLM-TTS (MIT weights), Chatterbox (MIT), Zonos (Apache 2.0), and NVIDIA Magpie (NVIDIA Open Model License, which does permit commercial use).
That list is longer than it looks from the leaderboard, which is the practical reason the previous section exists. The best model you can legally ship is Step Audio EditX at 1,102 Elo, 113 points off the top - but Qwen3-TTS and VoxCPM2 are unranked, permissive, heavily downloaded and quite possibly better. Evaluate those two yourself rather than reading down the Elo table until you hit a license you can live with.
How to self-host these models
Here’s the thing nobody says plainly: there is still no Ollama for TTS. Ollama itself has no text-to-speech support at all - the feature request has been open since June 2025 with no implementation. What has standardized is the API shape - almost everything now speaks OpenAI’s POST /v1/audio/speech dialect - but not the runtime. Every server wraps a different narrow subset of models, and none gives you Ollama’s one-binary, pull-any-model, no-Python experience.
The closest anyone has come is llama.cpp-omni, which runs VoxCPM2 from GGUF with no Python at all. One model, but the right shape.
A big part of why: no single library even contains the models people actually deploy. Hugging Face Transformers has text-to-waveform support for Bark, CSM, Higgs Audio v2, Qwen omni models, SeamlessM4T and VITS - but no Kokoro, no XTTS, no Chatterbox, no F5-TTS. The popular models each live in their own repo with their own inference path.
The servers worth using
| Tool | Best for | Models covered |
|---|---|---|
| LocalAI | Broadest coverage, one server for TTS + LLM + more | Coqui, Piper, Qwen3-TTS, VibeVoice, Chatterbox, fish-speech |
| vLLM-Omni | Production GPU serving, streaming, batching | Qwen3-TTS (all 5 variants), fishaudio/s2-pro, Voxtral-4B-TTS, VoxCPM2, CosyVoice3, OmniVoice, MOSS-TTS-Nano |
| llama.cpp-omni | GGUF on CPU, Metal, CUDA or Vulkan, no PyTorch | VoxCPM2 only |
| SGLang-Omni | The only path for Higgs Audio V3 | Higgs Audio V3, Fish S2 Pro |
| Kokoro-FastAPI | Fastest path to a working endpoint | Kokoro-82M only |
| kokoro-onnx | CPU and edge, no PyTorch dependency | Kokoro-82M only |
On vLLM specifically, the detail matters: core vLLM does not do TTS - its supported-models list treats audio as input only. Text-to-speech lives in a separate official subproject, vllm-omni, which is where you’ll find /v1/audio/speech, /v1/audio/voices, batch endpoints and a WebSocket streaming endpoint. If a tutorial tells you to serve Fish S2 Pro or Voxtral TTS from plain vLLM, it’s out of date.
A few more landmines worth knowing:
- openedai-speech is archived and dead, and one of the four successors its README recommends is itself long dead. Don’t start here.
- Piper moved orgs.
rhasspy/piperis archived; the live project is OHF-Voice/piper1-gpl. Several server projects still link the old repo. - Upstream llama.cpp’s
llama-ttsbinary is a dead end - pinned to OuteTTS-0.2-500M, a 2024-era model. Use the llama.cpp-omni fork and VoxCPM2 instead. - Speaches bills itself as “Ollama, but for TTS/STT” and is closest in spirit, but it only runs Kokoro and Piper and its
masterbranch has been quiet since April 2026. - Breeze TTS 2 has no server yet. The #1 model ships a PyTorch CLI, a single-concurrency streaming API and a Docker image. Need batching? You’re writing that layer yourself.
For the wider self-hosting picture, our guides on self-hosting any LLM and picking hardware for local models cover the GPU, quantization, and driver groundwork that applies here too.
Getting to your TTS server from outside your network
Once your model is serving on localhost:8880 or wherever, you’ll usually want to reach it from somewhere else - a phone, a staging app, a teammate, or an AI agent that needs a voice. A Pinggy tunnel is a one-liner for that:
ssh -p 443 -R0:localhost:8880 free.pinggy.ioThat prints a public HTTPS URL like https://abc123.a.pinggy.link pointing at your local endpoint, so an OpenAI-compatible client can hit /v1/audio/speech on it from anywhere without you opening a port or configuring a reverse proxy. We’ve written this up in more depth for Voicebox, a local-first AI voice studio, and for Kokoro running on a free Colab GPU.
Quick decision guide
| Your Need | Recommended Model | Why |
|---|---|---|
| Best quality, full stop | Breeze TTS 2 | 1,215 Elo, above ElevenLabs Eleven v3, on a 12GB card - but the weights are non-commercial |
| Best quality you can ship | Step Audio EditX | Highest-ranked Apache 2.0 model at 1,102; evaluate Qwen3-TTS and VoxCPM2 alongside it |
| High volume on a budget | Kokoro 82M | Top-six quality from 82M params; runs on a CPU for the price of electricity |
| Cloning a specific voice | Voxtral TTS | Wins the Controlled Voice Arena among open weights from a 3-second reference; Chatterbox if you need MIT |
| Fine-grained emotion direction | Fish Audio S2 Pro or Step Audio EditX | Inline free-form tags vs iterative token-space editing |
| Multilingual and commercial | VoxCPM2 or Chatterbox | 30 and 23 languages, Apache 2.0 and MIT respectively |
| Widest language coverage | Higgs Audio V3 TTS | 100+ languages with published per-benchmark WER; non-commercial |
| A voice with no reference audio | Qwen3-TTS VoiceDesign or Maya1 | Describe the speaker in text, no consent problem to manage, both Apache 2.0 |
| Voice agents, one consistent voice | Magpie-Multilingual 357M | Fixed speakers by design, 357M params, commercial-safe |
| Highest audio fidelity | VoxCPM2 | Native 48kHz output, above Zonos's 44kHz and everyone else's 24kHz |
| No GPU at all | Kokoro or VoxCPM2 | Kokoro via ONNX, VoxCPM2 via llama.cpp-omni GGUF; neither needs PyTorch |
Conclusion
This summer the open-weight models caught the closed ones. Breeze TTS 2 outranks ElevenLabs’ $100-per-million flagship, Voxtral TTS clones a voice better than anything else you can download, and Kokoro still does a startling amount of it in 82 million parameters on a CPU. Cartesia’s Sonic 3.6 is still ahead of all of them, and if voice quality is the product you sell, pay for it - but that’s a narrower slice of use cases than it sounds.
Three things to get right. Read the license on the weights, not the landing page - the GitHub badge says Apache 2.0 for models you cannot ship. Don’t stop at the leaderboard, because two of the best permissively licensed models here aren’t on it. And budget your time for the serving layer, not the model - there’s still no Ollama for TTS.