Pinggy Blog

Tunnels, networking, self-hosted LLMs, and AI news

Hands-on guides, protocol deep dives, and field notes on tunnels, SSH, reverse proxies, self-hosting, self-hosted LLMs, and AI - from the people building Pinggy.


ZuckOff: The Bluetooth Fingerprint That Gives Away Meta's Camera Glasses

Smart Glasses Privacy Bluetooth

ZuckOff is a free app that listens for the Bluetooth broadcasts camera glasses give off and matches them against a catalogued list of manufacturer IDs. Here is exactly how the detection works, what it can't tell you, and why a solo developer built it.
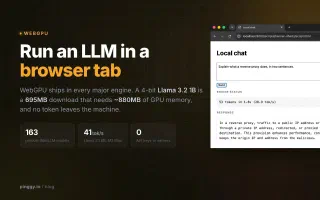
Run an LLM Inside a Browser Tab: WebGPU and Local Inference in 2026

WebGPU Local LLM Web Development

In-browser LLM inference works in 2026. WebGPU ships in every major engine, WebLLM 0.2.85 carries 163 prebuilt models, and a 4-bit Llama 3.2 1B is a 695MB download needing ~880MB of GPU memory. Working code, real numbers, and the limits.

AI Workflow Automation: When to Buy and When to Build Your Own Tools

Workflow Automation AI Tools Automation

AI workflow automation: when an off-the-shelf tool is enough and when building your own is worth it. Budget, urgency, scalability and how specific your requirements are decide the answer more than the technology does.

TypeSafe Jev: Top 3 Use Cases and How It Compares to OpenAI and Anthropic Models

AI Models API LLM

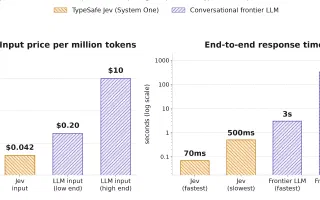
TypeSafe's Jev is a System One model that returns typed decisions instead of text: 70-500ms latency, $0.042 per million input tokens with output free, and 0% structured-output errors. Here are the three jobs it actually fits, the honest benchmark picture against GPT-6 Astra and Claude, and the tasks where it is the wrong tool.

Small LLMs That Fit in 8GB: The Best Models to Self-Host in 2026

Local LLM Self-Hosted AI Ollama

Which open-weight LLMs actually fit in 8GB of VRAM or RAM in 2026, with measured file sizes, KV cache math from published configs, and Ollama commands for Qwen3.5, Gemma 4, Ministral 3, Granite 4.1, Nemotron 3 Nano, and Phi-4-mini.